News and insights on edge AI
Releases and notes from the team.
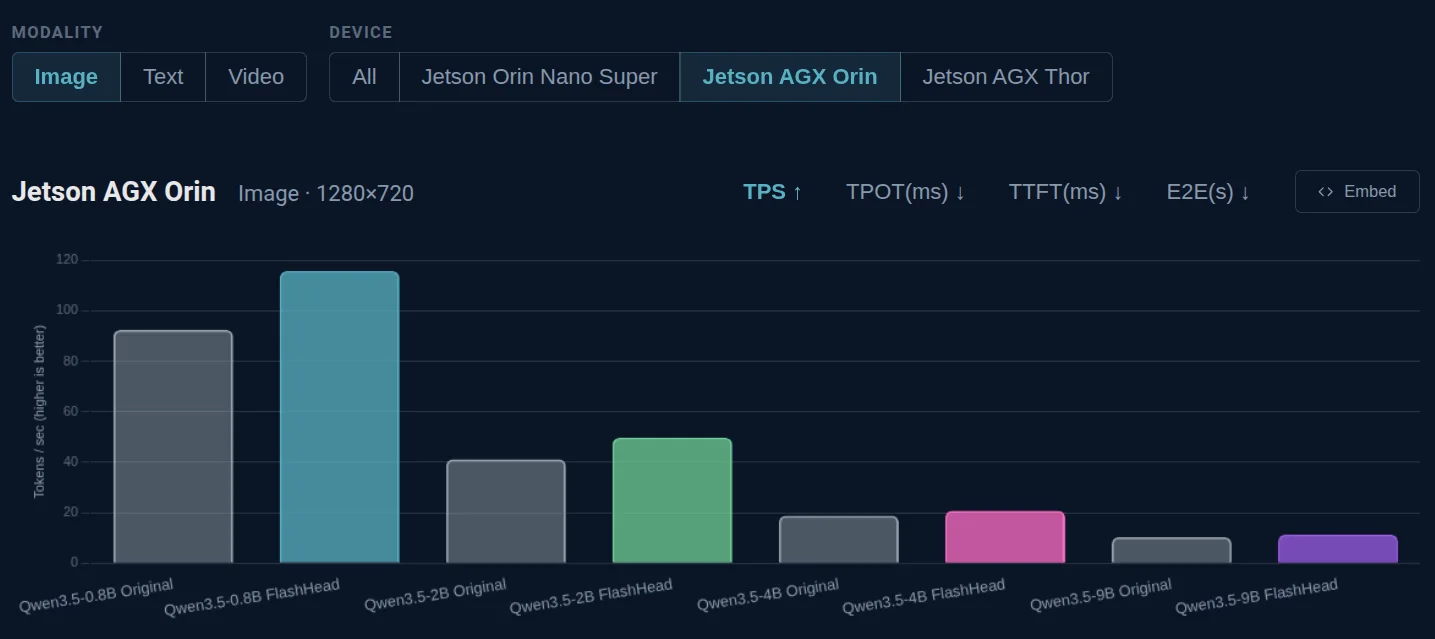 ReleasesQwen 3.5 Optimized with FlashHead
Discover how Qwen 3.5, optimized with FlashHead, achieves faster inference speeds without sacrificing quality, making it ideal for edge computing.
Embedl··1 min read
 ReleasesIntroducing hfviewer
Discover hfviewer, a tool that simplifies model architecture exploration in the Hugging Face ecosystem, enhancing understanding and collaboration in AI development.
Embedl··2 min read
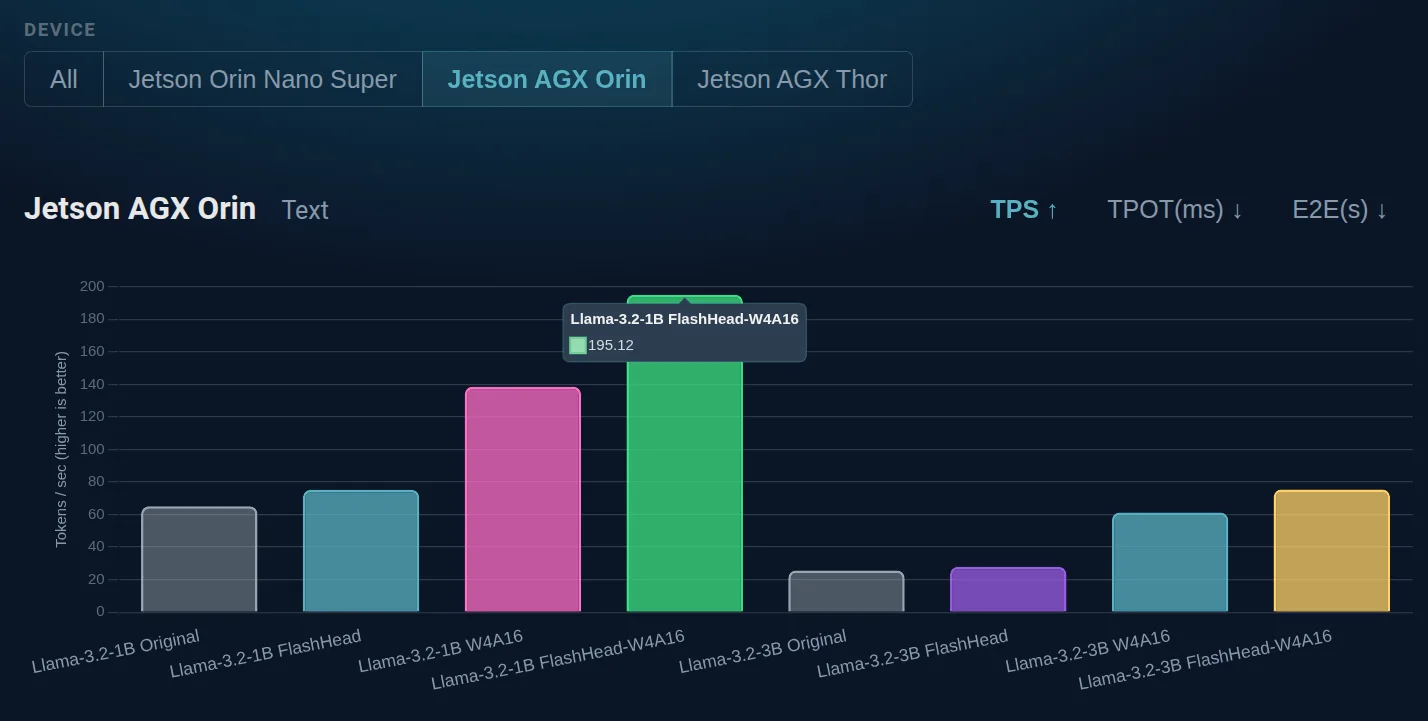 ReleasesFlashHead for vLLM, made simple
Discover how FlashHead simplifies integration with vLLM, enhancing model performance and reducing latency without complex setups. Explore the benefits now.
Embedl··8 min read
 ReleasesLightning-Fast Multimodal Edge Inference with Under 8GB RAM
Embedl is releasing Cosmos Reason2 with FlashHead, a new optimized model that delivers fast multi-modal reasoning on devices with less than 8GB of RAM while maintaining strong reasoning performance.
Embedl··3 min read
 ReleasesCosmos Reason 2 Without the Quantization Trade-Off
Discover how our latest model, W4A16-Edge2, achieves full baseline reasoning accuracy for edge deployment without the usual trade-offs in memory and latency.
Embedl··3 min read
 ReleasesBlackwell-optimized Cosmos Reason 2
New Cosmos Reason 2 variant optimized for NVIDIA Jetson AGX Thor offers efficient NVFP4 quantization, boosting edge AI performance and maintaining reasoning quality. Discover more in our latest release.
Embedl··2 min read
 ReleasesCosmos Reason 2, Quantized for the Edge
Release of optimized Cosmos Reason 2 model for Jetson Nano Super, enhancing multimodal reasoning on constrained edge devices with improved performance and memory efficiency.
Embedl··1 min read
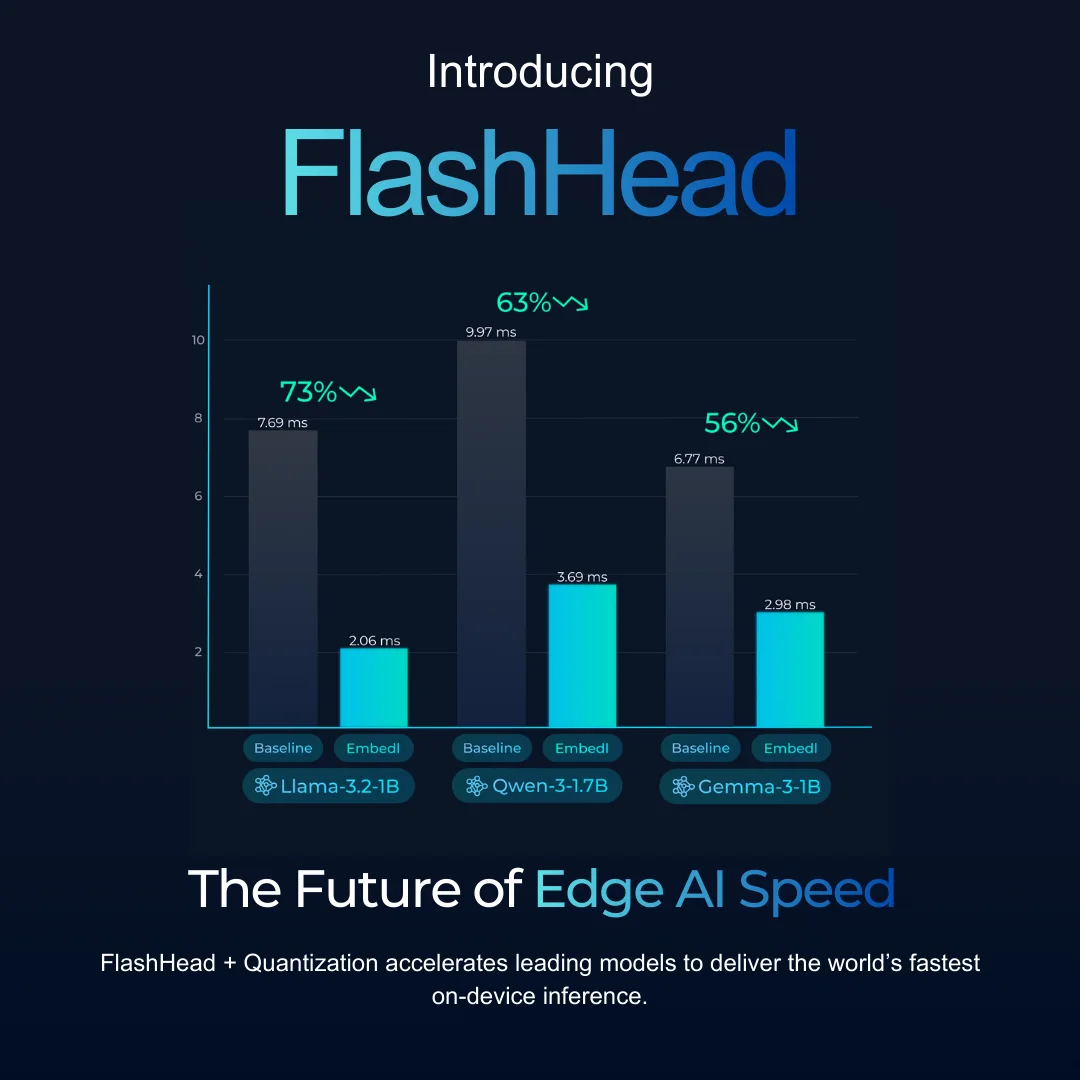 ReleasesUltra-Efficient SLMs: Embedl’s Breakthrough for On-Device AI
Embedl's FlashHead revolutionizes efficient on-device AI by optimizing classification heads in LLMs, leading to faster, scalable, and more accurate models for edge devices.
Embedl··5 min read
 ReleasesEDGE AI Talks: Faster Time-To-Device with Embedl Hub
Learn how Embedl Hub streamlines AI deployment to edge devices by overcoming hardware fragmentation, reducing trial-and-error, and enabling faster, reliable performance profiling.
Embedl··7 min read
 ReleasesAmazon releases AZ1 Neural Edge Processor
On September 24th, Amazon held its annual hardware event, introducing their new generation of smart home hubs, speakers and other gadgets.
Elaheh Malekzadeh··2 min read